Permutational Multivariate Analysis of Variance Using Distance Matrices
adonis.RdAnalysis of variance using distance matrices — for partitioning distance matrices among sources of variation and fitting linear models (e.g., factors, polynomial regression) to distance matrices; uses a permutation test with pseudo-\(F\) ratios.
Arguments
- formula
Model formula. The function can be called only with the formula interface. Most usual features of
formulahold, especially as defined inccaandrda. The LHS must be either a community data matrix or a dissimilarity matrix, e.g., fromvegdistordist. If the LHS is a data matrix, functionvegdistwill be used to find the dissimilarities. The RHS defines the independent variables. These can be continuous variables or factors, they can be transformed within the formula, and they can have interactions as in a typicalformula. The RHS can have a special termConditionthat defines variables to be “partialled out” before constraints, just like indbrdaorcca. This allows the use of partial `adonis2`.- data
the data frame for the independent variables, with rows in the same order as the community data matrix or dissimilarity matrix named on the LHS of
formula.- permutations
a list of control values for the permutations as returned by the function
how, or the number of permutations required, or a permutation matrix where each row gives the permuted indices.- method
the name of any method used in
vegdistto calculate pairwise distances if the left hand side of theformulawas a data frame or a matrix.- sqrt.dist
Take square root of dissimilarities. This often euclidifies dissimilarities.
- add
Add a constant to the non-diagonal dissimilarities such that all eigenvalues are non-negative in the underlying Principal Co-ordinates Analysis (see
wcmdscalefor details). Choice"lingoes"(orTRUE) use the recommended method of Legendre & Anderson (1999: “method 1”) and"cailliez"uses their “method 2”.- by
by = NULLwill assess the overall significance of all terms together,by = "terms"will assess significance for each term (sequentially from first to last), settingby = "margin"will assess the marginal effects of the terms (each marginal term analysed in a model with all other variables),by = "onedf"will analyse one-degree-of-freedom contrasts sequentially. The argument is passed on toanova.cca.- parallel
Number of parallel processes or a predefined socket cluster. With
parallel = 1uses ordinary, non-parallel processing. The parallel processing is done with parallel package.- na.action
Handling of missing values on the right-hand-side of the formula (see
na.failfor explanation and alternatives). Missing values are not allowed on the left-hand-side. NB, argumentsubsetis not implemented.- strata
Groups within which to constrain permutations. The traditional non-movable strata are set as Blocks in the permute package, but some more flexible alternatives may be more appropriate.
- permustat
The permutation statistic. The default
"pseudo-F"retains the ordinary pseudo-\(F\) test."modified-F"compares groups while allowing their within-group variation (dispersion) to differ. The argument name must be supplied in full.- groups
A factor identifying the groups to compare when
permustat = "modified-F". For a formula containing a single factor, that factor is used automatically. For a model with several factors and all their interactions, supply a factor identifying each combination of factor levels, for exampleinteraction(A, B)for the modelY ~ A * B. See Details for the supported models.- ...
Other arguments passed to
vegdist.
Details
adonis2 is a function for the analysis and partitioning sums of
squares using dissimilarities. The function is based on the principles
of McArdle & Anderson (2001) and can perform sequential, marginal and
overall tests. The function also allows using additive constants or
squareroot of dissimilarities to avoid negative eigenvalues, but can
also handle semimetric indices (such as Bray-Curtis) that produce
negative eigenvalues. The adonis2 tests are identical to
anova.cca of dbrda. With Euclidean
distances, the tests are also identical to anova.cca of
rda.
With permustat = "modified-F", the modified pseudo-\(F\)
statistic of Anderson et al. (2017) compares all groups in a one-way
analysis, allowing their within-group variation to differ. A model
containing several factors and all their interactions can also be used
for an overall test, treating each combination of factor levels as a
group. For example, Y ~ A * B with
groups = interaction(A, B) gives the same overall test as a
one-way analysis using the combined grouping factor. Supply this factor
in groups; it does not need to be added to the model formula.
All factors are treated as fixed. Separate tests of individual factors
or interactions are not currently supported.
There must be at least two groups and at least two observations in every
group. The modified test does not support continuous predictors, models
that omit interactions between factors, Condition terms,
by tests, or model = "full" permutations. Tests for mixed
or random-factor models would require further development.
The modified test is not available for cca or capscale.
Chi-square dissimilarities can instead be supplied explicitly to
adonis2 or dbrda when those dissimilarities are appropriate
for the analysis.
The modified test uses the same between-group and within-group sums of squares as the ordinary pseudo-\(F\) test. Instead of pooling within-group variation across all observations, it estimates variation separately for each group and combines these estimates using weights based on group sizes. The test statistic is recalculated for every permutation.
The residual degrees of freedom reported for the modified test use the Brown–Forsythe/Satterthwaite approximation and may be non-integer. The residual and total sums of squares, and hence \(R^2\), retain their usual definitions.
For a one-way model with a single response variable (and Euclidean
distances for distance-based analyses), permustat = "modified-F"
reduces to the Brown–Forsythe statistic for testing equality of group
means under unequal variances. This differs from Welch's test used by
oneway.test with var.equal = FALSE.
With two groups, the modified statistic equals the square of Welch's
\(t\) statistic from t.test, and its effective
denominator degrees of freedom agree with those of Welch's test.
With three or more groups, the statistics and denominator degrees of
freedom generally differ because the Brown–Forsythe and Welch methods
use different variance weighting and degrees-of-freedom approximations.
The univariate Brown–Forsythe statistic and denominator degrees of
freedom can be compared with onewaytests::bf.test(), described by
Dag et al. (2018).
The function partitions sums of squares of a multivariate data set,
and they are directly analogous to MANOVA (multivariate analysis of
variance). McArdle and Anderson (2001) and Anderson (2001) refer to
the method as “permutational MANOVA” (formerly
“nonparametric MANOVA”). Further, as the inputs are linear
predictors, and a response matrix of an arbitrary number of columns,
they are a robust alternative to both parametric MANOVA and to
ordination methods for describing how variation is attributed to
different experimental treatments or uncontrolled covariates. The
method is also analogous to distance-based redundancy analysis and
algorithmically similar to dbrda (Legendre and Anderson
1999), and provides an alternative to AMOVA (nested analysis of
molecular variance, Excoffier, Smouse, and Quattro, 1992; amova
in the ade4 package) for both crossed and nested factors.
Value
The function returns an anova.cca result object with a
new column for partial \(R^2\): This is the proportion
of sum of squares from the total, and in marginal models
(by = "margin") the \(R^2\) terms do not add up to
1.
Note
Anderson (2001, Fig. 4) warns that the method may confound
location and dispersion effects: significant differences may be caused
by different within-group variation (dispersion) instead of different
mean values of the groups (see Warton et al. 2012 for a general
analysis). However, it seems that adonis2 is less sensitive to
dispersion effects than some of its alternatives (anosim,
mrpp). Function betadisper is a sister
function to adonis2 to study the differences in dispersion
within the same geometric framework.
References
Anderson, M.J. 2001. A new method for non-parametric multivariate analysis of variance. Austral Ecology, 26: 32–46.
Anderson, M.J., Walsh, D.C.I., Clarke, K.R., Gorley, R.N. and Guerra- Castro, E. 2017. Some solutions to the multivariate Behrens–Fisher problem for dissimilarity-based analyses. Australian & New Zealand Journal of Statistics, 59: 57–79.
Dag, O., Dolgun, A. and Konar, N.M. (2018). onewaytests: An R Package for One-Way Tests in Independent Groups Designs. The R Journal, 10(1): 175–199. https://journal.r-project.org/articles/RJ-2018-022/.
Excoffier, L., P.E. Smouse, and J.M. Quattro. 1992. Analysis of molecular variance inferred from metric distances among DNA haplotypes: Application to human mitochondrial DNA restriction data. Genetics, 131:479–491.
Legendre, P. and M.J. Anderson. 1999. Distance-based redundancy analysis: Testing multispecies responses in multifactorial ecological experiments. Ecological Monographs, 69:1–24.
McArdle, B.H. and M.J. Anderson. 2001. Fitting multivariate models to community data: A comment on distance-based redundancy analysis. Ecology, 82: 290–297.
Warton, D.I., Wright, T.W., Wang, Y. 2012. Distance-based multivariate analyses confound location and dispersion effects. Methods in Ecology and Evolution, 3, 89–101.
Examples
data(dune)
data(dune.env)
## default is overall (omnibus) test
adonis2(dune ~ Management*A1, data = dune.env)
#> Permutation test for adonis under reduced model
#> Permutation: free
#> Number of permutations: 999
#>
#> adonis2(formula = dune ~ Management * A1, data = dune.env)
#> Df SumOfSqs R2 F Pr(>F)
#> Model 7 2.4987 0.58122 2.3792 0.004 **
#> Residual 12 1.8004 0.41878
#> Total 19 4.2990 1.00000
#> ---
#> Signif. codes: 0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1
## sequential tests
adonis2(dune ~ Management*A1, data = dune.env, by = "terms")
#> Permutation test for adonis under reduced model
#> Terms added sequentially (first to last)
#> Permutation: free
#> Number of permutations: 999
#>
#> adonis2(formula = dune ~ Management * A1, data = dune.env, by = "terms")
#> Df SumOfSqs R2 F Pr(>F)
#> Management 3 1.4686 0.34161 3.2629 0.002 **
#> A1 1 0.4409 0.10256 2.9387 0.019 *
#> Management:A1 3 0.5892 0.13705 1.3090 0.225
#> Residual 12 1.8004 0.41878
#> Total 19 4.2990 1.00000
#> ---
#> Signif. codes: 0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1
## Published omnibus test allowing heterogeneous dispersions
data("norwegianShelf")
take23 <- norwegianShelf$area %in% c("2", "3")
shelf23 <- 1L * (norwegianShelf$comm[take23, , drop = FALSE] > 0L)
area23 <- droplevels(norwegianShelf$area[take23])
shelf.perms <- rbind(rev(seq_len(nrow(shelf23))),
c(2:nrow(shelf23), 1))
adonis2(shelf23 ~ area23, method = "jaccard", binary = TRUE,
permutations = shelf.perms, permustat = "modified-F")
#> Permutation test for adonis under reduced model
#> Modified pseudo-F allowing heterogeneous dispersions
#> Permutation: supplied matrix
#> Number of permutations: 2
#>
#> adonis2(formula = shelf23 ~ area23, permutations = shelf.perms, method = "jaccard", binary = TRUE, permustat = "modified-F")
#> Df SumOfSqs R2 F Pr(>F)
#> Model 1.000 1.7613 0.12919 6.8388 0.3333
#> Residual 43.659 11.8717 0.87081
#> Total 45.000 13.6330 1.00000
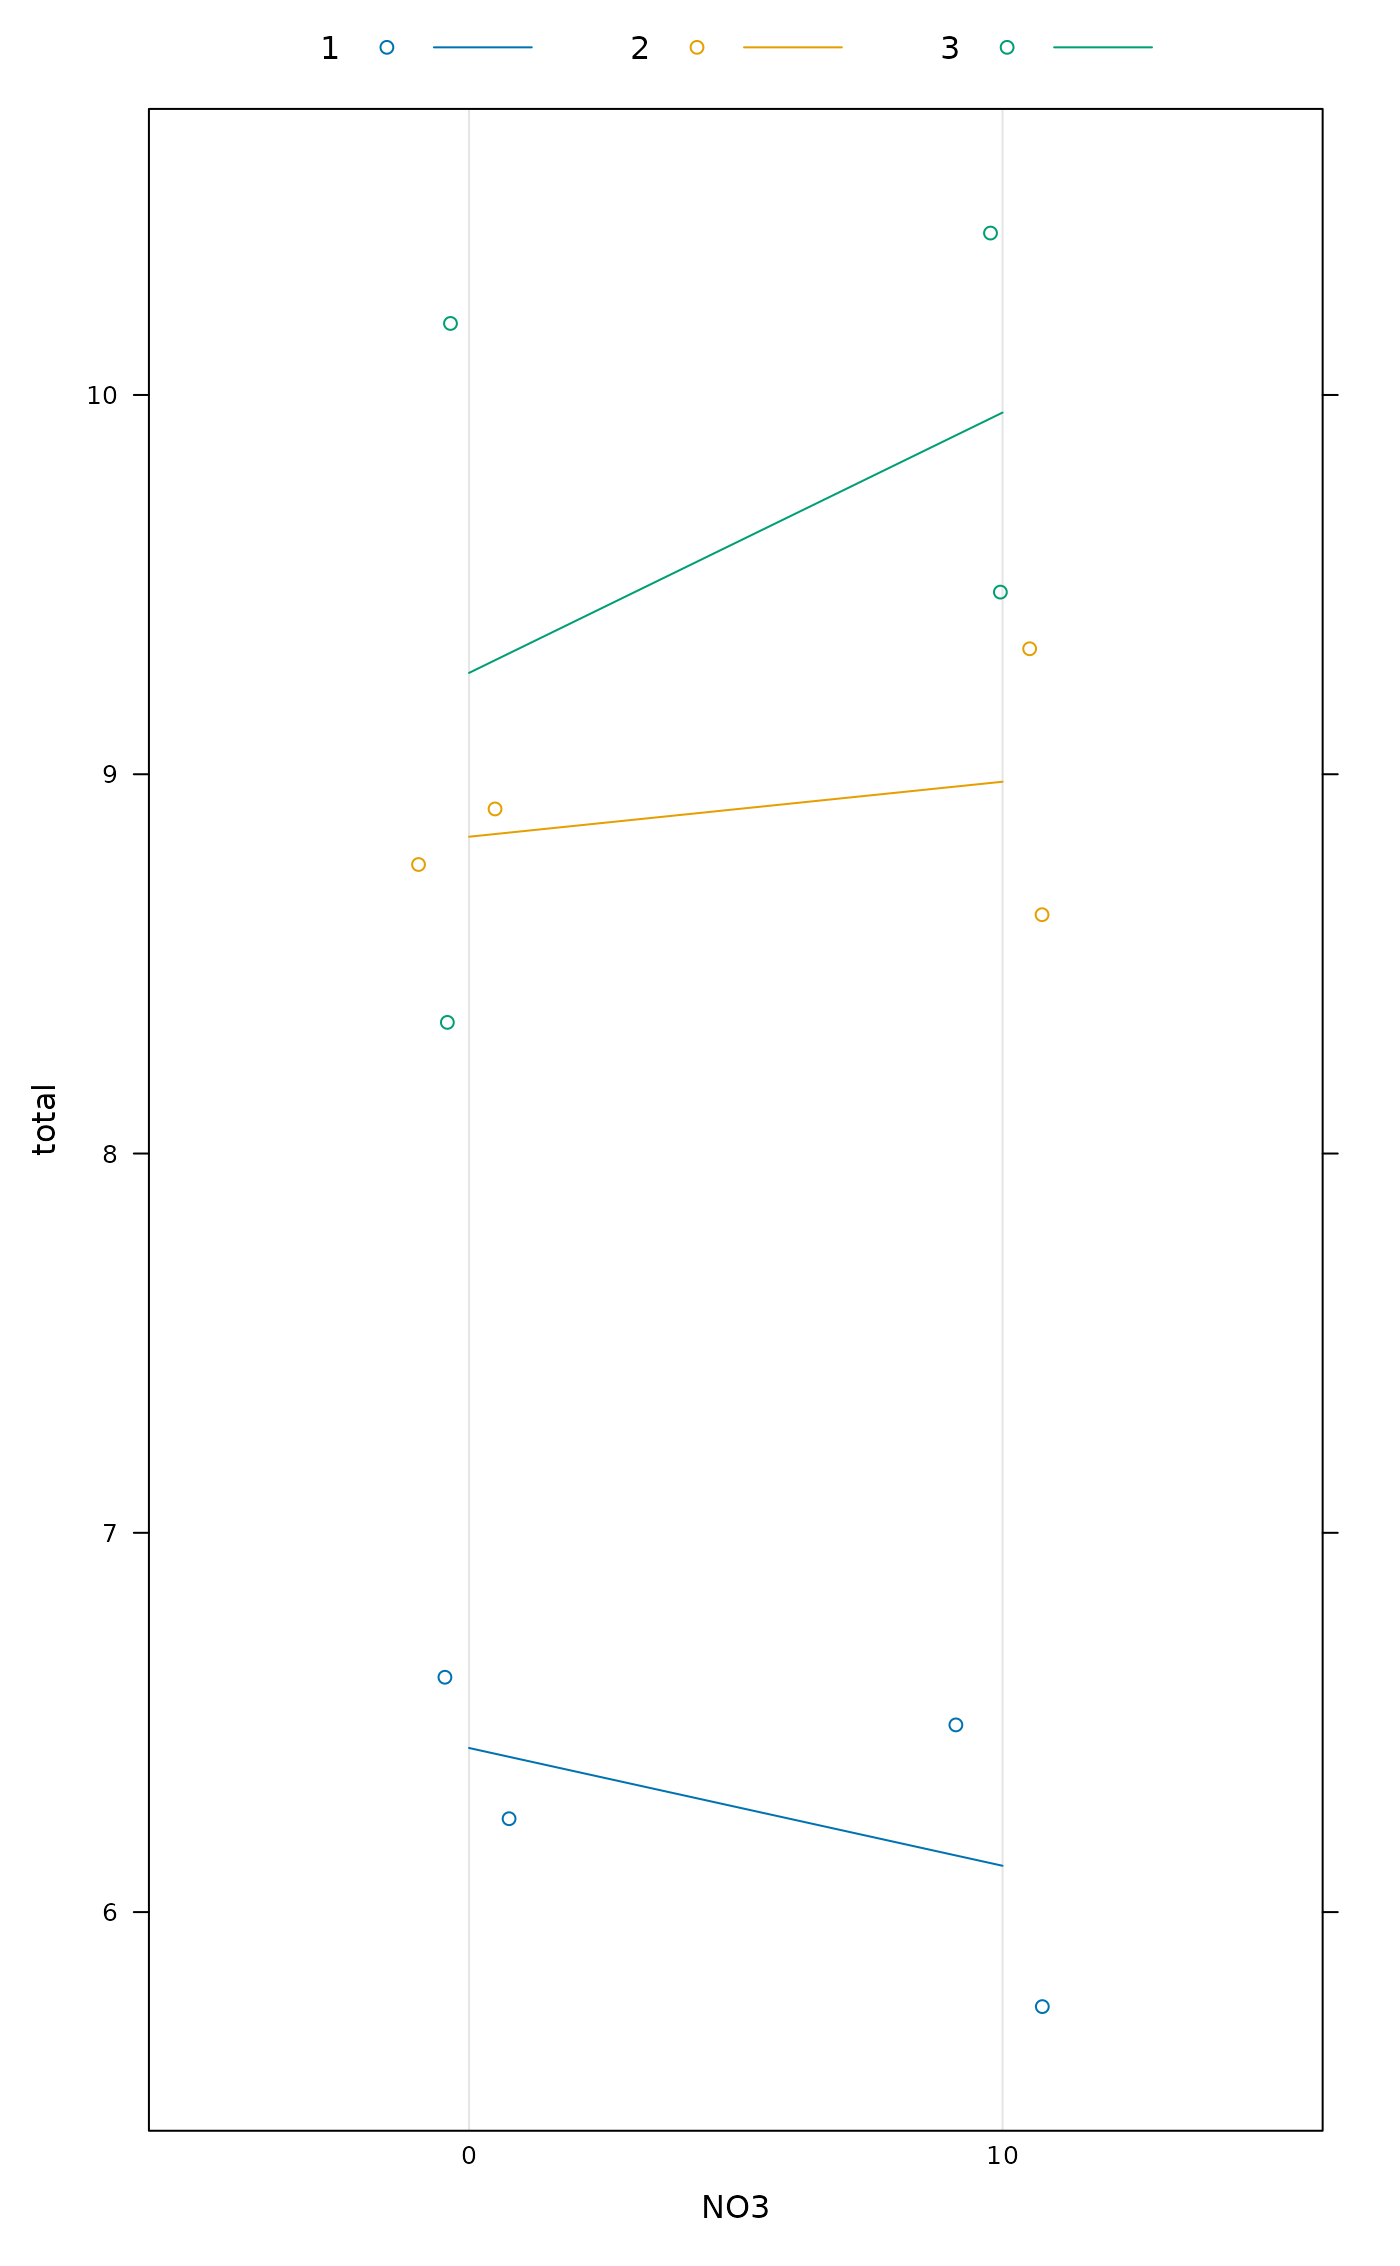
### Example of use with strata, for nested (e.g., block) designs.
dat <- expand.grid(rep=gl(2,1), NO3=factor(c(0,10)),field=gl(3,1) )
dat
#> rep NO3 field
#> 1 1 0 1
#> 2 2 0 1
#> 3 1 10 1
#> 4 2 10 1
#> 5 1 0 2
#> 6 2 0 2
#> 7 1 10 2
#> 8 2 10 2
#> 9 1 0 3
#> 10 2 0 3
#> 11 1 10 3
#> 12 2 10 3
Agropyron <- with(dat, as.numeric(field) + as.numeric(NO3)+2) +rnorm(12)/2
Schizachyrium <- with(dat, as.numeric(field) - as.numeric(NO3)+2) +rnorm(12)/2
total <- Agropyron + Schizachyrium
Y <- data.frame(Agropyron, Schizachyrium)
mod <- metaMDS(Y, trace = FALSE)
plot(mod)
### Ellipsoid hulls show treatment
with(dat, ordiellipse(mod, NO3, kind = "ehull", label = TRUE))
### Spider shows fields
with(dat, ordispider(mod, field, lty=3, col="red", label = TRUE))
 ### Incorrect (no strata)
adonis2(Y ~ NO3, data = dat, permutations = 199)
#> Permutation test for adonis under reduced model
#> Permutation: free
#> Number of permutations: 199
#>
#> adonis2(formula = Y ~ NO3, data = dat, permutations = 199)
#> Df SumOfSqs R2 F Pr(>F)
#> Model 1 0.02565 0.13671 1.5835 0.235
#> Residual 10 0.16198 0.86329
#> Total 11 0.18763 1.00000
## Correct with strata
with(dat, adonis2(Y ~ NO3, data = dat, permutations = 199, strata = field))
#> Permutation test for adonis under reduced model
#> Blocks: strata
#> Permutation: free
#> Number of permutations: 199
#>
#> adonis2(formula = Y ~ NO3, data = dat, permutations = 199, strata = field)
#> Df SumOfSqs R2 F Pr(>F)
#> Model 1 0.02565 0.13671 1.5835 0.015 *
#> Residual 10 0.16198 0.86329
#> Total 11 0.18763 1.00000
#> ---
#> Signif. codes: 0 ‘***’ 0.001 ‘**’ 0.01 ‘*’ 0.05 ‘.’ 0.1 ‘ ’ 1